
#FactCheck: Old Ukraine Blast Video Falsely Shared as Iran Strike on Israeli Nuclear Site
Executive Summary
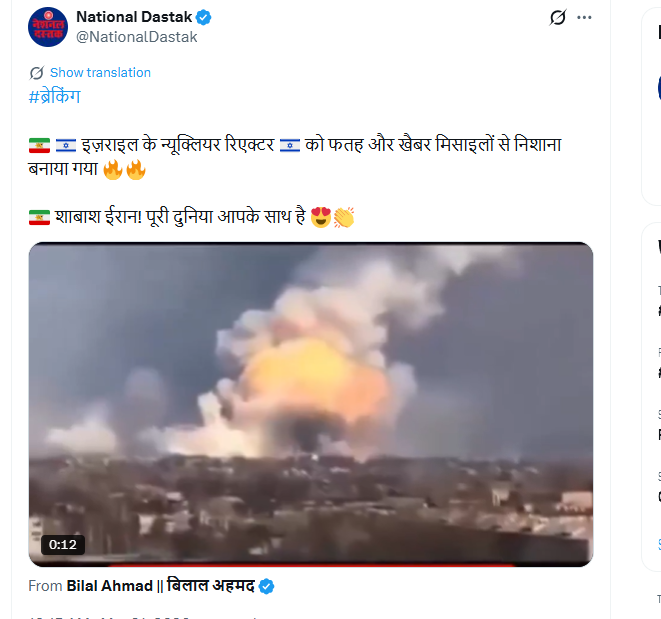
A video showing a massive fire and explosion is going viral on social media. The clip shows a large plume of smoke followed by a sudden blast. It is being shared with the claim that it depicts Iran attacking a nuclear reactor in Israel amid the ongoing Iran-Israel conflict. However, research by CyberPeace found that the claim is misleading. The viral video is actually from 2017 and shows a massive explosion at an ammunition depot in Ukraine.
Claim:
On social media platform X (formerly Twitter), a user shared the video on March 21, 2026, with the caption:“Israel’s nuclear reactor was targeted with Fateh and Khyber missiles. Well done Iran! The whole world is with you.”
Fact Check:
To verify the viral claim, we extracted keyframes from the video and conducted a reverse image search. During this process, we found the same video uploaded on March 23, 2017, on a YouTube channel named “null.” According to the upload, the video shows a massive explosion at an ammunition depot in Balakliya, Ukraine. Using these clues, we performed a keyword search and found a report published on March 24, 2017, by Global News.
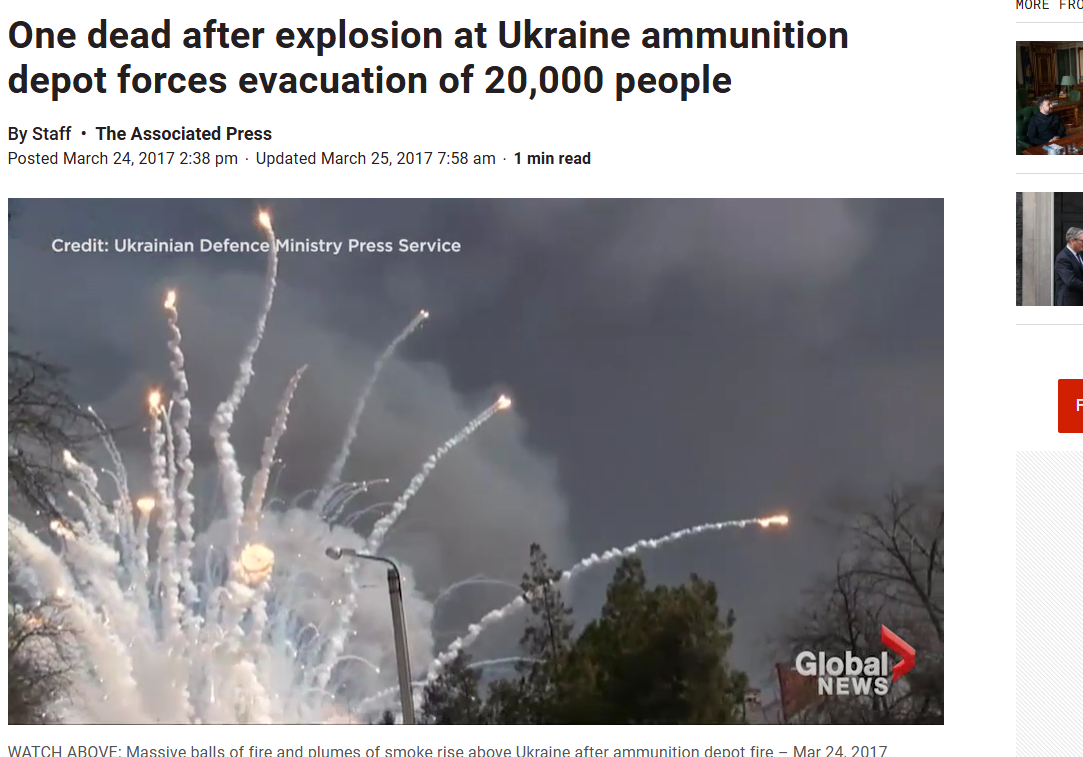
According to the report, a major fire and explosion broke out at a large military ammunition depot in Balakliya, located in Ukraine’s Kharkiv region. The incident resulted in one death, while nearly 20,000 people from surrounding areas were evacuated to safer locations.
Conclusion:
The claim that the video shows Iran attacking a nuclear reactor in Israel is misleading. The viral footage is actually from 2017 and depicts an explosion at an ammunition depot in Ukraine.

Related Blogs

As AI language models become more powerful, they are also becoming more prone to errors. One increasingly prominent issue is AI hallucinations, instances where models generate outputs that are factually incorrect, nonsensical, or entirely fabricated, yet present them with complete confidence. Recently, ChatGPT released two new models—o3 and o4-mini, which differ from earlier versions as they focus more on step-by-step reasoning rather than simple text prediction. With the growing reliance on chatbots and generative models for everything from news summaries to legal advice, this phenomenon poses a serious threat to public trust, information accuracy, and decision-making.
What Are AI Hallucinations?
AI hallucinations occur when a model invents facts, misattributes quotes, or cites nonexistent sources. This is not a bug but a side effect of how Large Language Models (LLMs) work, and it is only the probability that can be reduced, not their occurrence altogether. Trained on vast internet data, these models predict what word is likely to come next in a sequence. They have no true understanding of the world or facts, they simulate reasoning based on statistical patterns in text. What is alarming is that the newer and more advanced models are producing more hallucinations, not fewer. seemingly counterintuitive. This has been prevalent reasoning-based models, which generate answers step-by-step in a chain-of-thought style. While this can improve performance on complex tasks, it also opens more room for errors at each step, especially when no factual retrieval or grounding is involved.
As per reports shared on TechCrunch, it mentioned that when users asked AI models for short answers, hallucinations increased by up to 30%. And a study published in eWeek found that ChatGPT hallucinated in 40% of tests involving domain-specific queries, such as medical and legal questions. This was not, however, limited to this particular Large Language Model, but also similar ones like DeepSeek. Even more concerning are hallucinations in multimodal models like those used for deepfakes. Forbes reports that some of these models produce synthetic media that not only look real but are also capable of contributing to fabricated narratives, raising the stakes for the spread of misinformation during elections, crises, and other instances.
It is also notable that AI models are continually improving with each version, focusing on reducing hallucinations and enhancing accuracy. New features, such as providing source links and citations, are being implemented to increase transparency and reliability in responses.
The Misinformation Dilemma
The rise of AI-generated hallucinations exacerbates the already severe problem of online misinformation. Hallucinated content can quickly spread across social platforms, get scraped into training datasets, and re-emerge in new generations of models, creating a dangerous feedback loop. However, it helps that the developers are already aware of such instances and are actively charting out ways in which we can reduce the probability of this error. Some of them are:
- Retrieval-Augmented Generation (RAG): Instead of relying purely on a model’s internal knowledge, RAG allows the model to “look up” information from external databases or trusted sources during the generation process. This can significantly reduce hallucination rates by anchoring responses in verifiable data.
- Use of smaller, more specialised language models: Lightweight models fine-tuned on specific domains, such as medical records or legal texts. They tend to hallucinate less because their scope is limited and better curated.
Furthermore, transparency mechanisms such as source citation, model disclaimers, and user feedback loops can help mitigate the impact of hallucinations. For instance, when a model generates a response, linking back to its source allows users to verify the claims made.
Conclusion
AI hallucinations are an intrinsic part of how generative models function today, and such a side-effect would continue to occur until foundational changes are made in how models are trained and deployed. For the time being, developers, companies, and users must approach AI-generated content with caution. LLMs are, fundamentally, word predictors, brilliant but fallible. Recognising their limitations is the first step in navigating the misinformation dilemma they pose.
References
- https://www.eweek.com/news/ai-hallucinations-increase/
- https://www.resilience.org/stories/2025-05-11/better-ai-has-more-hallucinations/
- https://www.ekathimerini.com/nytimes/1269076/ai-is-getting-more-powerful-but-its-hallucinations-are-getting-worse/
- https://techcrunch.com/2025/05/08/asking-chatbots-for-short-answers-can-increase-hallucinations-study-finds/
- https://en.as.com/latest_news/is-chatgpt-having-robot-dreams-ai-is-hallucinating-and-producing-incorrect-information-and-experts-dont-know-why-n/
- https://www.newscientist.com/article/2479545-ai-hallucinations-are-getting-worse-and-theyre-here-to-stay/
- https://www.forbes.com/sites/conormurray/2025/05/06/why-ai-hallucinations-are-worse-than-ever/
- https://towardsdatascience.com/how-i-deal-with-hallucinations-at-an-ai-startup-9fc4121295cc/
- https://www.informationweek.com/machine-learning-ai/getting-a-handle-on-ai-hallucinations
Introduction
In today’s digital world, data has emerged as the new currency that influences global politics, markets, and societies. Companies, governments, and tech behemoths aim to control data because it accords them influence and power. However, a fundamental challenge brought about by this increased reliance on data is how to strike a balance between privacy protection and innovation and utility.
In recognition of these dangers, more than 200 Nobel laureates, scientists, and world leaders have recently signed the Global Call for AI Red Lines. Governments are urged by this initiative to create legally binding international regulations on artificial intelligence by 2026. Its goal is to stop AI from going beyond moral and security bounds, particularly in areas like political manipulation, mass surveillance, cyberattacks, and dangers to democratic institutions.
One way to address the threat to privacy is through pseudonymization, which makes it possible to use data valuable for research and innovation by substituting personal identifiers for artificial ones. Pseudonymization thus directly advances the AI Red Lines initiative's mission of facilitating technological advancement while lowering the risks of data misuse and privacy violations.
The Red Lines of AI: Why do they matter?
The Global Call for AI Red Lines initiative represents a collective attempt to impose precaution before catastrophe, which was done with the objective of recognising the Red Lines in the use of AI tools. Thus, anything that unites the risks of using AI is due to the absence of global safeguards. Some of these Red Lines can be understood as;
- Cybersecurity breaches in the form of exposure of financial and personal data due to AI-driven hacking and surveillance.
- Occurrence of privacy invasions due to endless tracking.
- Generative AI can also help to create realistic fake content, undermining the trust of public discourses, leading to misinformation.
- Algorithmic amplification of polarising content can also threaten civic stability, leading to a demographic disruption.
Legal Frameworks and Regulatory Landscape
The regulations of Artificial Intelligence stand fragmented across jurisdictions, leaving significant loopholes aside. Some of the frameworks already provide partial guidance. The European Union’s Artificial Intelligence Act 2024 bans “unacceptable” AI practices, whereas the US-China Agreement also ensures that nuclear weapons remain under human, not machine-controlled. The UN General Assembly has adopted resolutions urging safe and ethical AI usage, with a binding and elusive global treaty.
On the front of data protection, the General Data Protection Regulations (GDPR) of EU offers a clear definition of Pseudonymisation under Article 4(5). It also describes a process where personal data is altered in a way that it cannot be attributed to an individual without additional information, which must be stored securely and separately. Importantly, pseudonymised data still qualifies as “personal data” under GDPR. However, India’s Digital Personal Data Protection Act (DPDP) 2023 adopts a similar stance. It does not explicitly define pseudonymisation in broad terms, such as “personal data” by including potentially reversible identifiers. According to Section 8(4) of the Act, companies are meant to adopt appropriate technical or organisational measures. International bodies and conventions like the OECD Principles on AI or the Council of Europe Convention 108+ emphasize accountability, transparency, and data minimisation. Collectively, these instruments point towards pseudonymization as a best practice, though interpretations of its scope differ.
Strategies for Corporate Implementation
For a company, pseudonymisation is not just about compliance, it is also a practical solution that offers measurable benefits. By pseudonymising data, businesses can get benefits, such as;
- Enhancing Privacy protection by masking identifiers like names or IDs by reducing the impact of data breaches.
- Preserving Data Utility, unlike having a full anonymisation, pseudonymisation also retains patterns that are essential for analytical innovation.
- Facilitating data sharing can allow organizations to collaborate with their partners and researchers while maintaining proper trust.
According to these benefits, competitive advantages get translated to clauses where customers find it more likely to trust organizations that prioritise data protection, while pseudonymisation further enables the firms to engage in cross-border collaboration without violating local data laws.
Balancing Privacy Rights and Data Utility
Balancing is a central dilemma; on one side lies the case of necessity over data utility, where companies, researchers and governments rely on large datasets to enhance the scale of AI innovation. On the other hand lies the question of the right to privacy, which is a non-negotiable principle protected under the international human rights law.
Pseudonymisation offers a practical compromise by enabling the use of sensitive data while reducing the privacy risks. Taking examples of different domains, such as healthcare, it allows the researchers to work with patient information without exposing identities, whereas in finance, it supports fraud detection without revealing the customer details.
Conclusion
The rapid rise of artificial intelligence has led to the outpacing of regulations, raising urgent questions related to safety, fairness and accountability. The global call for recognising the AI red lines is a bold step that looks in the direction of setting universal boundaries. Yet, alongside the remaining global treaties, practical safeguards are also needed. Pseudonymisation exemplifies such a safeguard, which is legally recognised under the GDPR and increasingly relevant in India’s DPDP Act. It balances the twin imperatives of privacy, protection, and data utility. For organizations, adopting pseudonymisation is not only about ensuring regulatory compliance, rather, it is also about building trust, ensuring resilience, and aligning with the broader ethical responsibilities in this digital age. As the future of AI is debatable, the guiding principles also need to be clear. By embedding techniques for preserving privacy, like pseudonymisation, into AI systems, we can take a significant step towards developing a sustainable, ethical and innovation-driven digital ecosystem.
References
https://www.techaheadcorp.com/blog/shadow-ai-the-risks-of-unregulated-ai-usage-in-enterprises/
https://planetmainframe.com/2024/11/the-risks-of-unregulated-ai-what-to-know/
https://cepr.org/voxeu/columns/dangers-unregulated-artificial-intelligence
https://www.forbes.com/sites/bernardmarr/2023/06/02/the-15-biggest-risks-of-artificial-intelligence/
Executive Summary
A CCTV video showing a man being shot is being widely circulated on social media with the claim that it depicts the killing of Lashkar-e-Taiba terrorist Amir Hamza in Pakistan. However, research by the CyberPeace Research Wing found that the claim is misleading. The viral video existed online even before the reported attack on Amir Hamza.
Claim
Social media users are sharing a CCTV clip claiming that Lashkar-e-Taiba terrorist Amir Hamza was shot dead in Pakistan.
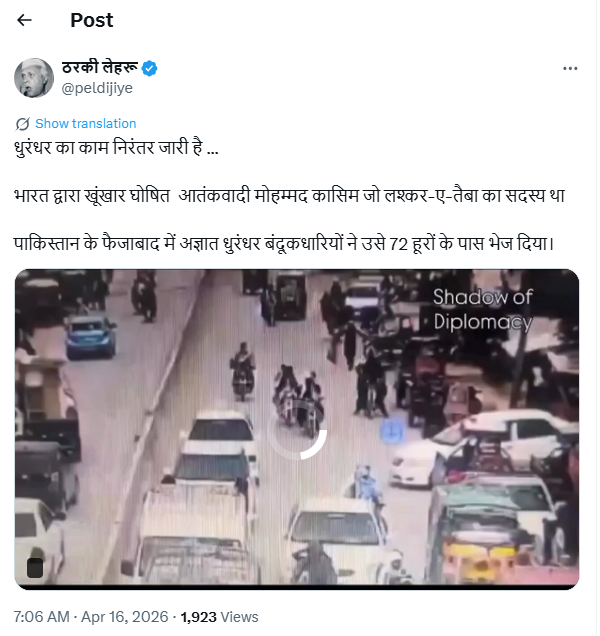
Fact Check
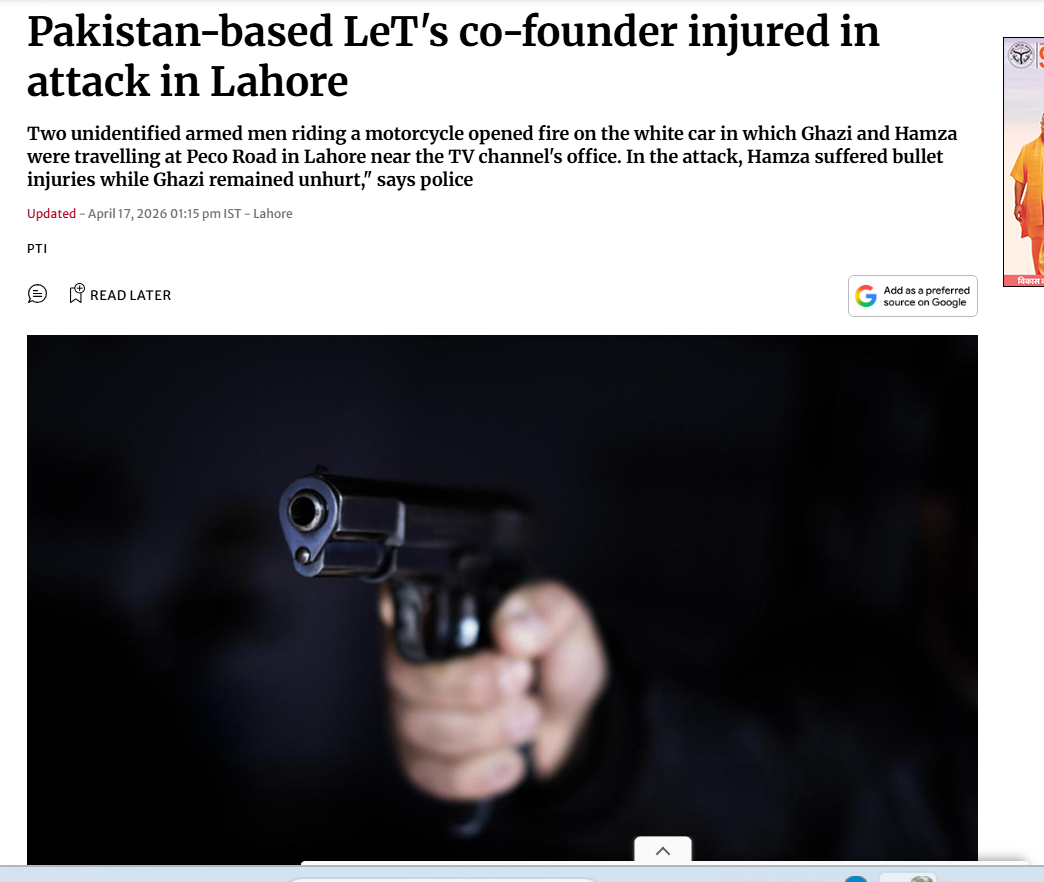
To verify the claim, we first searched relevant keywords such as “Maulana Amir Hamza firing Lahore.” This led us to a report published on April 17, 2026, by The Hindu. Citing Pakistani channel 24 News HD TV, the report stated that unidentified attackers opened fire on the car of TV host Justice Nazir Ahmed Ghazi. Amir Hamza was injured in the incident, not killed.
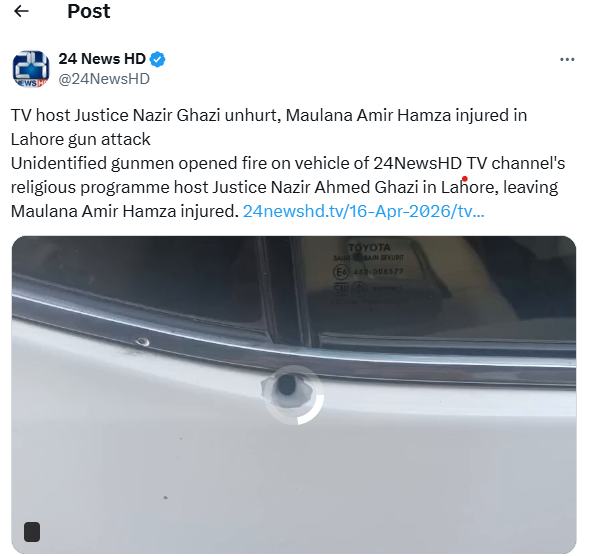
We also reviewed the official social media accounts of 24 News HD TV. A post on its X handle (@24NewsHD) confirmed that Justice Ghazi was safe, while Amir Hamza sustained injuries in the firing incident in Lahore.
For further verification, we extracted keyframes from the viral video and performed a reverse image search. The same clip was found uploaded on March 28, 2026, on a Pakistani Facebook page. According to the post, the CCTV footage was linked to the killing of an individual named Saifullah Malakhel.
Although we could not independently verify the exact origin of the video, our findings clearly indicate that the footage predates the recent attack on Amir Hamza and is unrelated to the incident.
Conclusion
The viral claim is false. Amir Hamza was not killed but reportedly injured in the firing incident, as per credible media reports. The CCTV video being shared in this context is old and unrelated, and has been circulated with a misleading narrative.
